Extract Images from a PDF: 4 Methods That Keep the Original Quality
To extract images from a PDF, use a tool that exports the embedded image streams at their original resolution instead of re-rendering the page. A converter or a screenshot produces a re-encoded copy at screen quality. Below: the four methods compared, the pitfalls that ruin quality, and how to verify the result.
Exporting an image and capturing one are not the same operation
A PDF is not a picture of a document: it is a container. Each photo, each chart, each scanned page it holds was imported as an independent file, with its own encoding, its own pixel dimensions, sometimes its own color profile. The page layout simply says where to place it and at what size.
Extracting an image from a PDF means recovering that embedded file as is, at the resolution it was imported with. Converting a PDF to images, on the other hand, means photographing the rendered page at the resolution of the moment. The same brochure can yield a 300 DPI photo with the first approach and a blurry 96 DPI copy with the second.
This distinction explains most of the disappointment people have with PDF-to-image converters. The tool did its job: it rendered the page. It is just that the rendering was never the goal. If the plan is to reuse the pictures, in a presentation, on a website, in another document, extraction is the operation you want.
The 4 methods to extract images from a PDF
Four approaches actually work. They differ in fidelity, in throughput, and in what happens to your file along the way:
| Method | Original quality kept? | All images at once? | When to use it |
|---|---|---|---|
| Dedicated offline tool | Yes, streams exported untouched | Yes, one pass | Batches and private documents, the reference method |
| Command line (pdfimages) | Yes, raw streams | Yes, one command | Automation, if the terminal holds no secrets for you |
| PDF reader (Preview, Acrobat) | Preview: no, a displayed copy. Acrobat: yes, via a paid export | No, one image at a time | Grabbing a single visual quickly |
| Online converter | Rarely: page re-render, then re-compression | Yes | Disposable files, never private ones |
Two honest notes on the free routes. pdfimages, from the poppler toolkit, is lossless and exports everything, but it hands you the raw internals of the file: transparency masks can arrive as separate black-and-white files, and exotic encodings produce formats your image viewer may not open. Readers like Preview work picture by picture and hand you a copy of what is displayed, which is fine for a quick logo and wrong for anything you intend to print or publish. For regular use, a dedicated offline PDF editor with a proper export avoids the acrobatics.
Extract all images from a PDF in four steps
Here is the process with DocuNest's image extraction tool, built into the unified editor; the logic stays the same in other serious software.
Open the document in the editor
Drag your PDF into DocuNest. The file opens as is: no conversion, no upload, no account. It never leaves your computer.
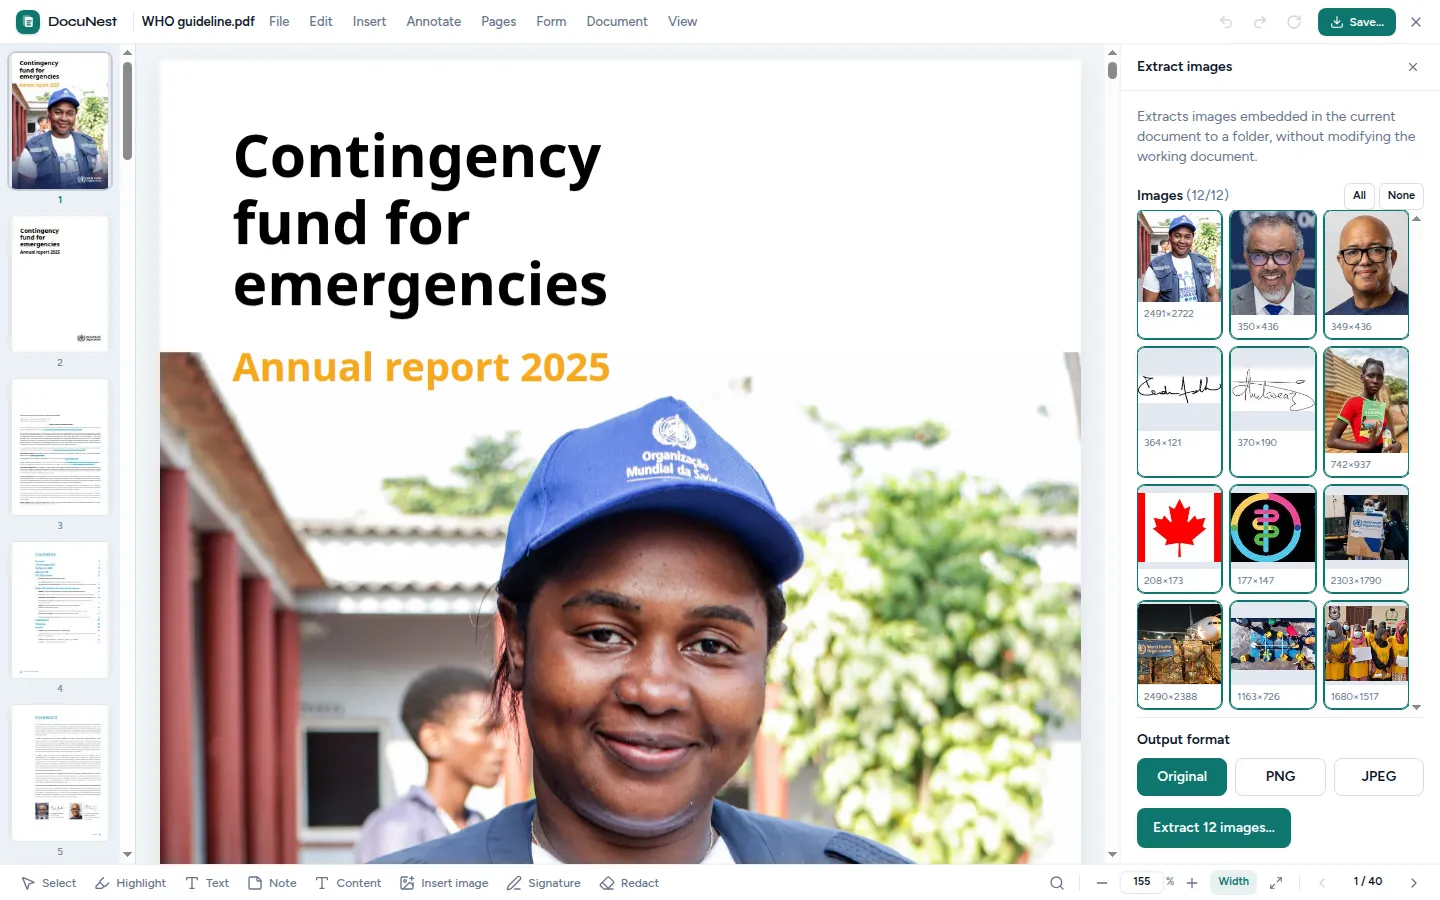
Choose Document, then Export, then Embedded images
One menu entry gathers every bitmap embedded in the file, in reading order, whatever their size or position on the page.
Pick the output format
PNG for screenshots, diagrams and anything with flat colors, JPEG for photographs, WebP to keep the weight down on the web. The resolution is always the original one: there is no recompression step.
Collect your images
All the images are written to the folder of your choice, each one as an independent file, ready to reuse. For the command-line minded, the same operation is scriptable:
docunest pdf extract-images -i document.pdf -o images/ --format png
Why your extracted images come out blurry, rotated, or incomplete
Three recurring complaints, three distinct causes. Blurry: the tool rendered the page instead of exporting the stream, then compressed its own render. The fix is a real extractor; the check is the pixel count, which should match the original file, not the screen size. Rotated: some PDFs store an image sideways and apply the correction only at display time. Extractors that ignore the stored orientation hand you a sideways picture; DocuNest applies it so the image comes out upright. Missing: what you took for an image may be a vector drawing or plain text, and there is simply no bitmap to extract. In that case, render the region to PNG instead of looking for a file that does not exist.
Online or offline: where your file goes during extraction
Think about what the images inside a PDF usually are: photos of people. Identity documents in an HR file, damage photos in an insurance claim, pictures of children in a school newsletter, property reports, medical letters. Extracting them online means uploading the whole document, photos included, to a server whose retention policy you do not control, so that copies of the file exist outside your machine before you have even seen the result.
Processing sensitive documents this way can also run into the GDPR's data-minimization principle: a remote copy is a new processing operation, with a new risk. Everything above works exactly the same offline: the file is parsed locally, the images are written to your disk, and no byte leaves the machine. We describe our approach to privacy on a dedicated page.
FAQ
What is the difference between extracting images from a PDF and converting the PDF to images?
Can you extract images from a PDF without losing quality?
How do I extract all images from a PDF at once?
How do I extract an image from a PDF on Mac or Windows without installing anything?
Why do some images fail to extract from a PDF?
To extract the images of your documents without sending them anywhere, the image extraction tool is built into DocuNest, a comprehensive PDF editor for a one-time fee of €30, with a 7-day free trial, no account required.